Engineering
Jev gets a vote, not a veto
Trinqa asks Jev — TypeSafe’s System One decision model — which Stellar payout route looks better, and then ignores it whenever it is slow, unsure, or being asked to do arithmetic. Here is the whole arrangement: the three layers, the weights, and every way the model gets overruled.
When you move money out of Trinqa to a local bank account, something has to choose how. On Stellar that means picking an anchor — the business that takes stablecoin on one side and pays out local currency on the other — and a rail inside it. Several may be able to serve the same withdrawal, and they differ in ways that matter: published fees, minimum and maximum amounts, estimated settlement time, whether the anchor is answering health checks at all, and whether your identity checks have cleared there.
Some of that is arithmetic. Some of it is judgment. Our position is that those two should never be done by the same thing.
Why not just ask an LLM
The obvious move is to hand the candidate list to a general model and ask which is best. We did not want that, for three reasons.
A chat model answers in prose, so you have to parse the answer, and parsing can fail at the exact moment money is moving. It takes seconds when the user is watching a spinner. And most importantly, it makes a text generator the thing that decides where funds go, with no natural boundary around how much of that decision it owns. The interesting question was never "can a model pick a route" — it is how little of the decision a model needs in order to be useful.
What Jev is
Jev is TypeSafe's first "System One" model. It does not generate text. You give it a state and a set of named, typed questions, and it returns typed answers with calibrated probabilities and a confidence score. There are three question types: choice (pick one of these options), score (place this on a rubric), and noul (is this statement true, 0–1). Every question is evaluated in parallel against the same state in one call.
Because the answer is constrained to the shape you declared, a malformed or invented answer is not something you have to defend against — the model cannot return one. TypeSafe reports end-to-end responses in the 70–500 ms range, with input priced at $0.042 per million tokens and output unmetered. An independent write-up puts typical calls near 100 ms and makes the point we agree with: it is a component inside ordinary application code, not a thing that runs the workflow.
The shape of it
A traditional model gives you a paragraph you must interpret. Jev gives you a number you can compare, plus a confidence you can threshold on. That difference is what makes it safe to put near a payment — not that it is smarter, but that its output has edges.
Three layers, in order
Our route decision has exactly three stages, and the model appears in only one of them.
Where Jev sits in a payout decision
Candidates in on the left, one chosen route out on the right. Only the middle stage involves a model — and the decision completes whether or not that stage answers.
Deterministic filter
Drops routes that cannot serve this request — wrong currency, below the minimum, above the maximum, identity checks not cleared.
Jev advises
Scores five judgment factors on a rubric we wrote, each answer carrying its own confidence.
Deterministic score
Our weights, our arithmetic. Ranks what survived and picks the winner.
1. A deterministic filter
Before anything is judged, routes that simply cannot serve the request are dropped, each with a recorded reason: the currency is not supported, withdrawals are not supported, the amount is below the minimum or above the maximum, the anchor is missing the connection we need, it is unavailable, identity checks have not cleared, or it is not in a state that can actually execute. These are facts about the request and the anchor's own published metadata. No judgment is involved, so no model is involved.
The reasons survive into the app. A route that was dropped is shown as dropped, with the clause that caused it — "caps payouts below this amount", "needs identity checks to be completed first" — rather than quietly disappearing from a list.
2. Jev advises — on five factors out of seven
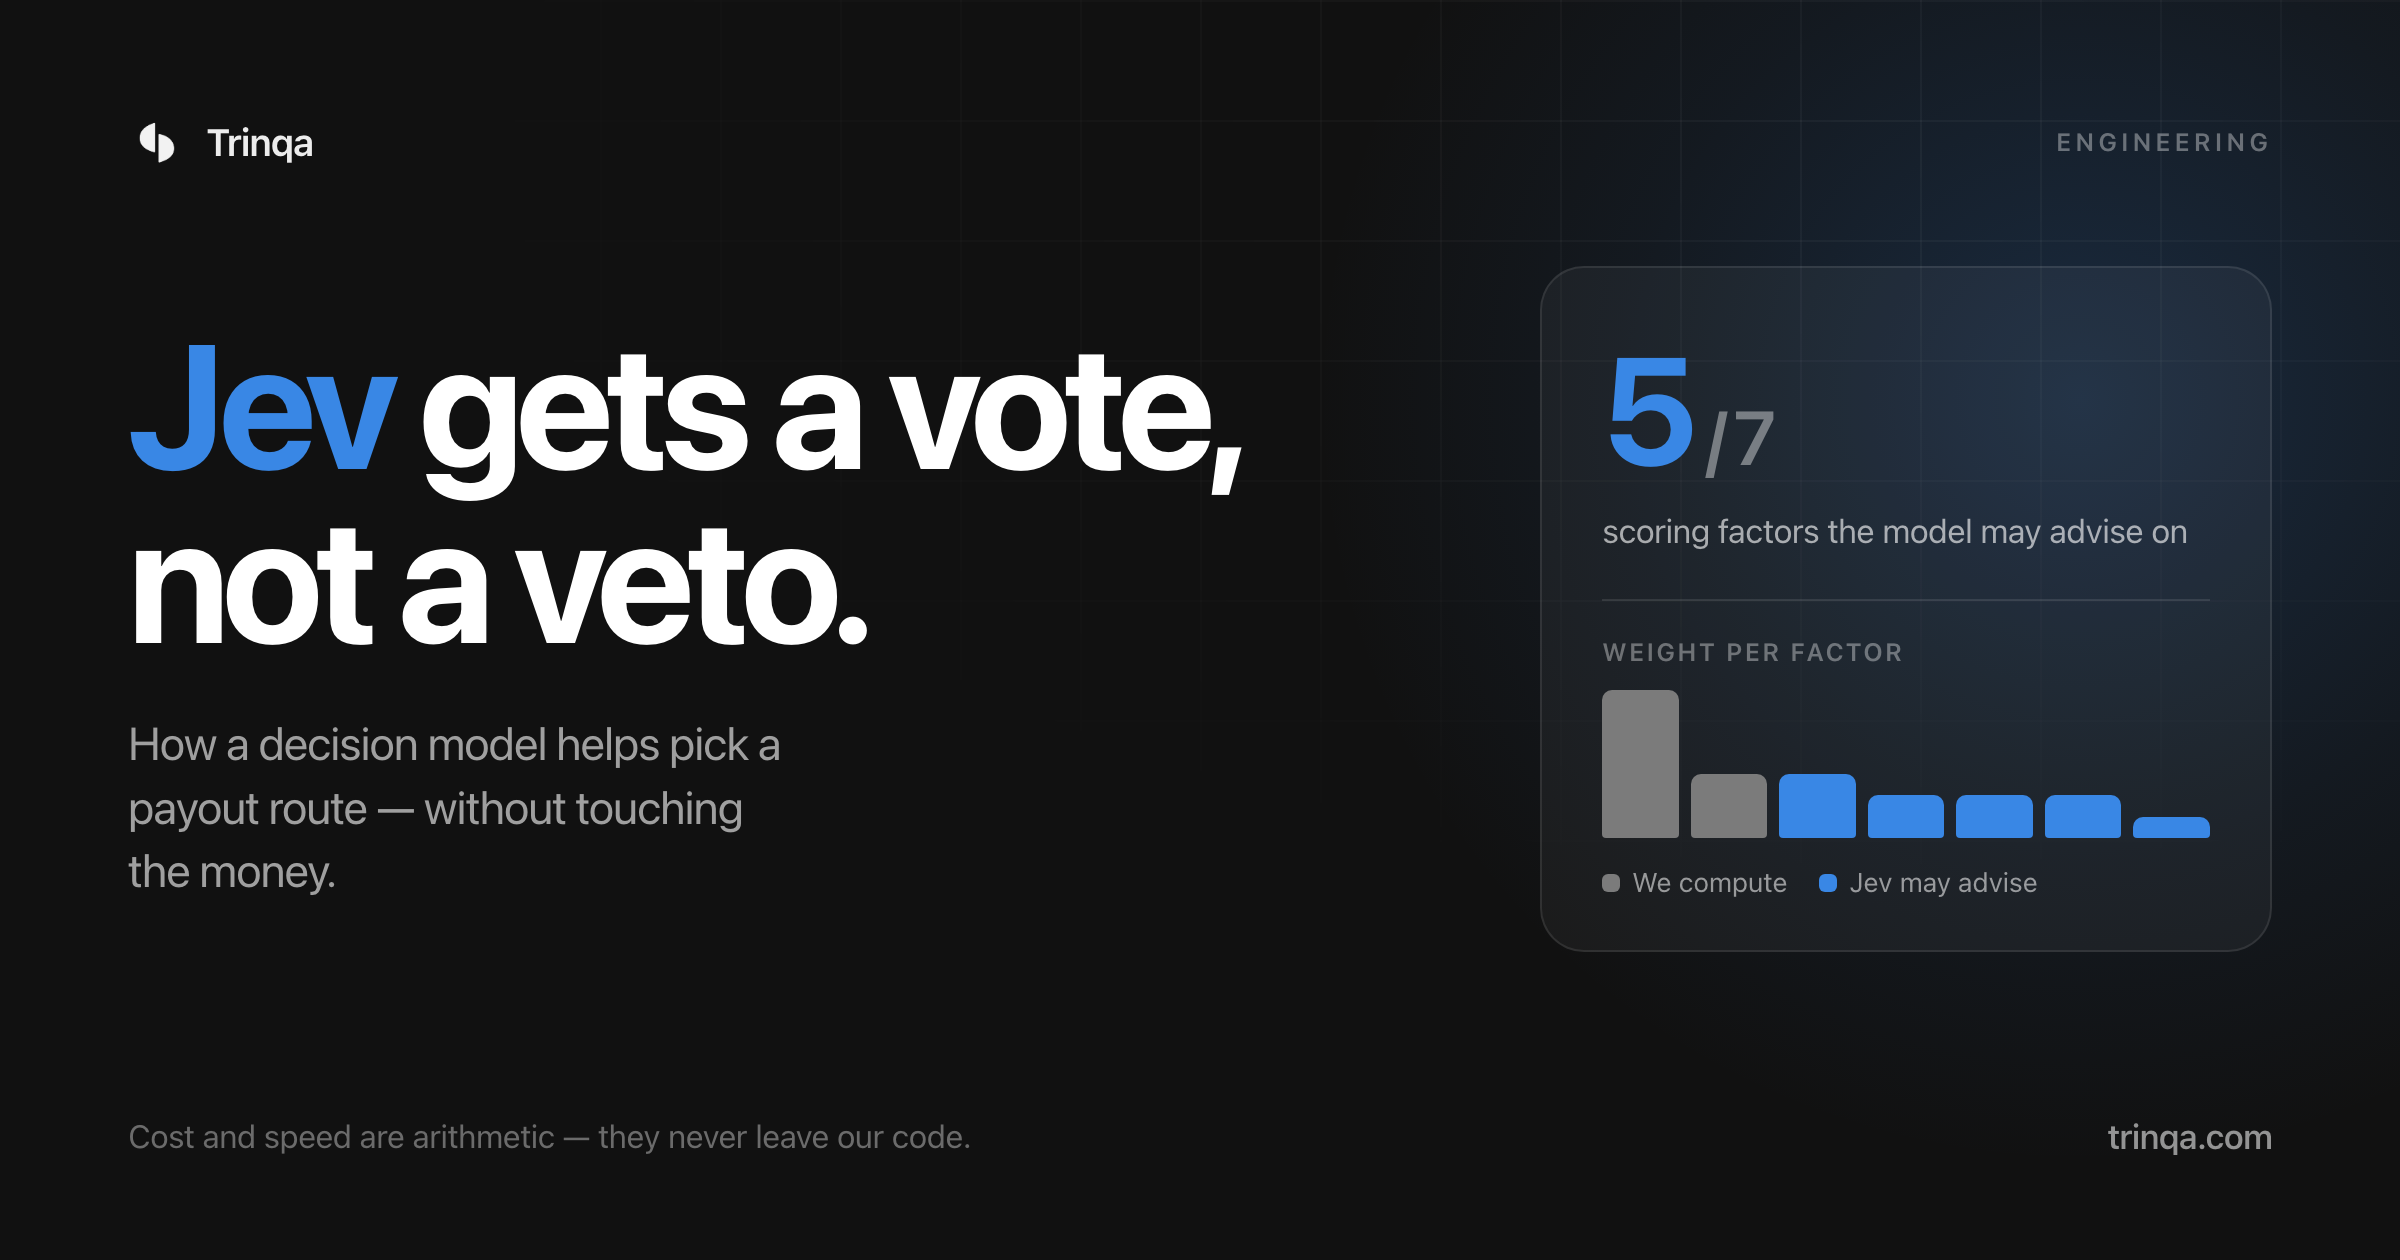
Every surviving candidate is scored on seven factors, each 0–100, combined with fixed weights that sum to 100. Jev is allowed to influence five of them. It is never asked about the other two.
The seven factors, and who produces each number
Weights are fixed, sum to 100, and live in our code. Jev may influence five of them — never the two that are arithmetic.
Show as a table
| Factor | Weight | Who produces it |
|---|---|---|
| Cost | 35 | Arithmetic, in our code |
| Speed | 15 | Arithmetic, in our code |
| Reliability | 15 | Jev may advise |
| Room under the limit | 10 | Jev may advise |
| Fits your timing | 10 | Jev may advise |
| Fits your risk setting | 10 | Jev may advise |
| Effect on your earnings | 5 | Jev may advise |
Cost and speed are excluded on purpose. Cost is a fee percentage plus a fixed fee plus any spread in the quote, divided by the amount; speed is settlement minutes. That is arithmetic on published numbers, and TypeSafe's own guidance on Jev's rough edges is blunt about it: keep the arithmetic in code. The same page notes that this model's score levels are weak in numerical calibration and should not be used to interpolate exact values. So the two heaviest factors, carrying half the weight between them, are computed from fee schedules and estimated minutes and never leave our code.
What is left is the part that is genuinely judgment — how much to trust an anchor's health signal, whether the amount sits comfortably inside the limits, whether this route's pace suits someone who needs the money in four days rather than four weeks. Each is sent as a score question against a five-level rubric we wrote, lowest first:
"r0_liquidity": {
  "type": "score",
  "instructions": "Judge how comfortably the requested amount fits within
                   this route's published rail limits (min/max), given in
                   `state`. Do not perform the arithmetic comparison
                   precisely yourself; give a qualitative judgment of
                   headroom.",
  "criteria": [
    "Requested amount is far outside the published min/max limits.",
    "Requested amount is close to a limit boundary, little headroom.",
    "Fits within limits, but headroom is unclear or only moderate.",
    "Comfortably fits within limits with good headroom.",
    "Fits with ample headroom, well within both min and max."
  ]
}
Note what the instruction says: do not do the comparison precisely, give a qualitative judgment. We are asking for the thing it is good at and explicitly waving it off the thing it is not. The answer comes back as a score on that rubric plus a confidence, and we normalise it to 0–100 using the legend the model returns when it has one, falling back to the rubric length we sent. When more than one route survives the filter we also ask a single choice question — which route would you recommend, on these judgment factors only — and use the answer for nothing but a line of rationale attached to the winner.
The state is deliberately thin — the request, and for each route only its name, status, estimated minutes, reliability signal, fee fields, and rail limits. TypeSafe documents that accuracy falls as unrelated detail accumulates in the state, because it acts as a distractor. So nothing goes in that a question does not need.
3. Deterministic scoring, with our weights
Whatever comes back, the final score is Σ (weight × factor) / 100, using weights that live in our code and are not in the request, not in the response, and not negotiable by the model. Jev can move five inputs. It cannot move the formula, and it cannot move what those inputs are worth.
Every way the model gets overruled
The interesting part of this design is not the call. It is everything around the call.
What one answer has to survive to count
Four gates, applied in order. Failing any of them costs that answer its influence — never the decision.
Did it arrive in time?
2.5s in the adapter, 3s on the whole call. A late answer is simply not there.
Did it parse?
Unknown or missing fields drop that route’s advice rather than throwing.
Is confidence ≥ 0.6?
Checked per factor, so one uncertain judgment does not discard the confident ones beside it.
Then it is used — and labelled
The factor is marked advisor; everything else stays deterministic.
timeoutlow_confidenceinvalid_outputerrordisabledno_routes
Whichever gate closed, the decision records why in one of those six names, and scoring carries on without the advice.
- Confidence is a gate, not a decoration. A factor answered below 0.6 confidence is dropped, and the advice that is handed on carries the mean confidence of the factors that survived — so the route-level threshold reflects what is actually being used.
- A slow advisor loses its vote. The adapter times out at 2.5 seconds, the scorer races the whole call at 3. Nobody waits on a spinner because a model is thinking.
- Every failure has a name. When advice is not used, the decision records why:
timeout,low_confidence,invalid_output,error,disabled,no_routes. The route still gets chosen — deterministically — and the reason is in the payload. - Unknown fields drop advice, not requests. The response is parsed defensively; anything we do not recognise costs that route its advice instead of throwing.
- Every number is labelled by origin. Each scored route carries a per-factor source:
deterministicoradvisor. The app reads that and changes what it says about the number, so "a model judged this" and "we calculated this" are never shown as the same kind of claim. - The advisor never signs anything. It returns scores. Execution is gated separately — by the policy contract and by your approval. There is no path from a model's answer to a signed transaction.
Turn Jev off entirely and Trinqa still picks a route. That is the test we held the design to: the model is an improvement to a system that works without it, not a dependency the system is built around.
What we are not claiming
Honest limits
- This runs on testnet today. The route planner, the advisor and the anchor directory are live in the build; real money is not.
- Our own baseline for timing fit and risk fit is neutral unless the app sends a target date and a risk setting, and the earnings-impact factor is not measured on our side at all. Those three carry 25 points of weight on a signal that is, for now, thinner than the weight suggests.
- We have not benchmarked Jev against a general model on our own labelled route decisions. TypeSafe's calibration claims are theirs, and the honest position is that calibrated probabilities need validating against your own data before you lean on them.
- Jev 1.13 has documented rough edges beyond arithmetic: dates read as text rather than ordered quantities, sensitivity to double negatives and indirection, and no adversarial reading of its own state. We designed around the ones that touch us and wrote the instructions as directly as we could.
The general shape
Strip out the anchors and the stablecoins and there is a pattern here that has nothing to do with payments.
Decide first which parts of a decision are arithmetic and which are judgment. Compute the arithmetic. For the judgment, ask a model questions with edges — a rubric, an enumerated choice, a boolean — instead of asking for an opinion in prose. Take a confidence score with each answer and set a threshold you are willing to defend. Keep the weights. Put a timeout on the whole thing. Record why you ignored it when you did. Then label, in whatever you show the user, which numbers a model touched.
None of that requires trusting the model. That is the point: we would rather build something whose correctness does not depend on the model being right, and then let a model make it better.
Trinqa is in early access
Money that keeps working until you need it. Join the waitlist and we will reach out when your spot is ready.
Sources
- TypeSafe AI — Introducing System One Models & Jev (latency, pricing, what a System One model is)
- TypeSafe AI docs — Introduction (the choice / score / noul question types, confidence versus probability)
- TypeSafe AI docs — Jev 1.13 jaggedness ("keep the arithmetic in code", distractors, indirection, numeric calibration)
- Flavio Copes — A deep dive into Jev (independent latency and cost figures, and where it fits next to an LLM)